

TL;DR
If your product runs an LLM agent harness on real time inference, you’re paying the realtime tax on work that is not prioritized. Cleaning transcripts, generating CRM summaries, synthesizing daily research digests, batching lead-funnel reports — all of it gets funneled through a synchronous, low-latency API that was priced for interactive chat.
The token economics are challengine by an order of magnitude. This article walks through how Frontier-tech’s open source voice-agent pipeline Sarthak (accessible as demo on https://frontiertech.vercel.app/contact).
Inferrence Trillema:
Building an inference pipeline is a strict trilemma between scalability, tokenomics, and workflow efficiency. Even with the relentless Moore’s-law equivalent gains of the last few years (MLA attention, MoE routing, speculative decoding, paged-attention KV-caches, hardware-level sparsity), still the trillema has become hard to navigate with even growing specs.
Users expect real-time interactive quality on benchmark models at premium prices — and the neoclouds and aggregator APIs respond with pricing wars, which is a zero-sum game for everyone. The mistake is treating every LLM call as a realtime call.
Doubleword (formerly TitanML) has built the most flexible inference infrastructure solve exactly these issues. They expose three explicit SLAs through one OpenAI-compatible API and providing the following category of inferrence services based on the result:
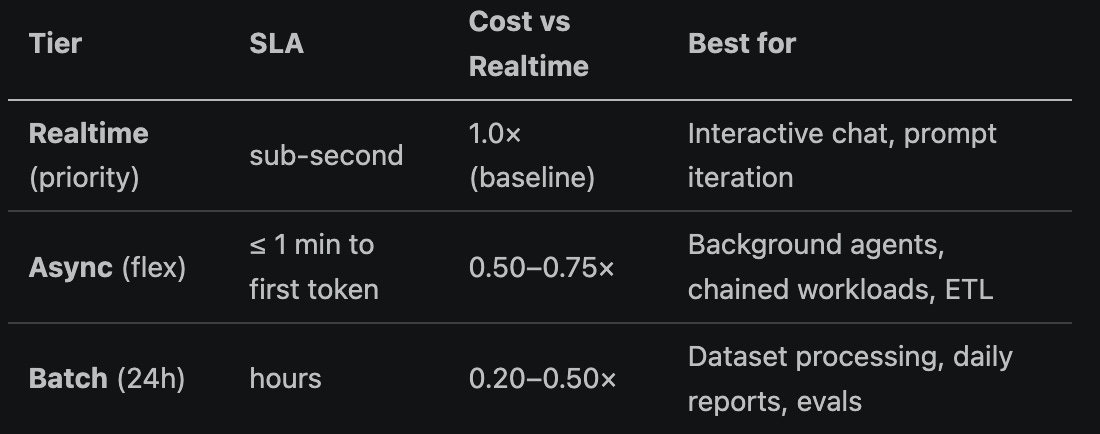
The flex tier is the the major unlock for my personal usecase: a deep-research workload that would cost $5.81 on OpenAI GPT-4o or $7.25 on Anthropic Sonnet 3.5 costs $0.34 on Doubleword flex API — the same Qwen 235B model, the same 1M context window is 16–20× cheaper vis a vis openrouter reference pipeline. I’ve used this pattern to flip a highly expensive feature (like background CRM enrichment) within 50 cents / day.
2. Technical architecture.
Sarthak is the add-on open source autonomous lead-agent that is:
🧰 Configurable out of the box voice agent for any website ( akin to intercom but currently still WIP).
🤖Ships with hermes agent harness: Lets you integrate your social media and online presence integrated with the model providers and persistence memory.
It replaces the standard contact form with a 5-minute voice (or chat) session that captures the prospect’s role, tech stack, budget band, timeline, and data-sovereignty requirements, then writes a structured lead report for the actual consultant ( in order to prepare for lead calls) by storing initial specs from harness into Twenty CRM.
The initial version’s workflow looks like this:
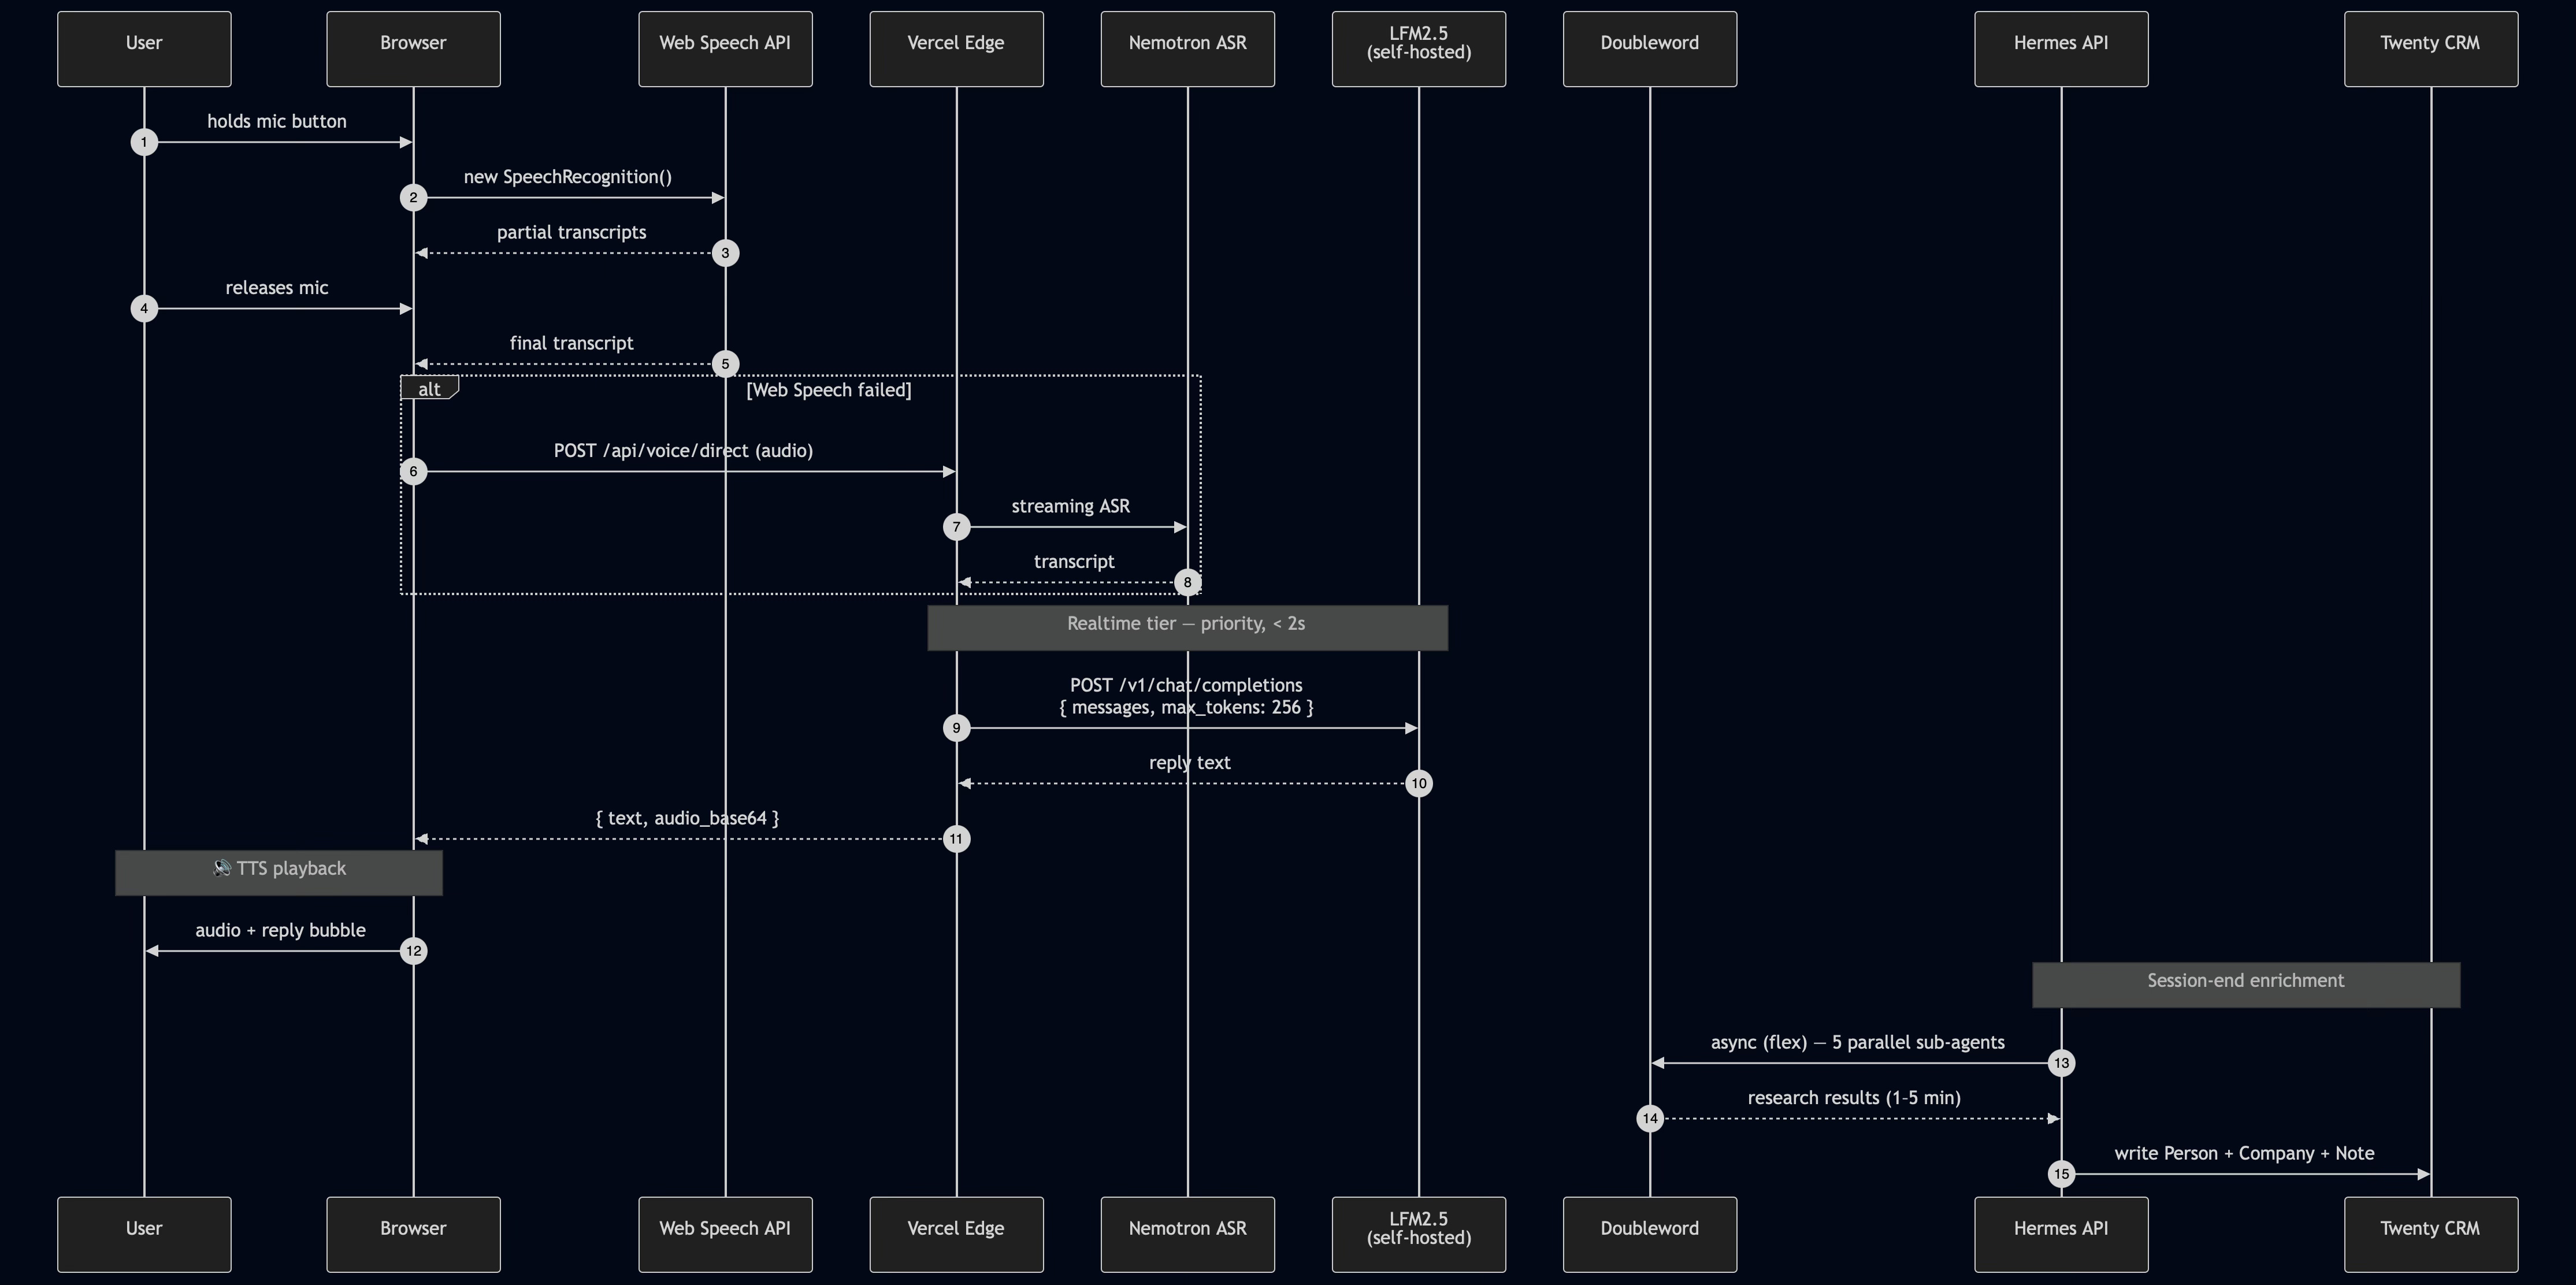
Now we will dig deep into each step:
Steps 1–3: The user speaks into their browser.
The user presses and holds a microphone button on the website. While they hold it, the browser listens to their voice and shows their words appearing on screen in real time — like a live caption. When they let go of the button, the browser saves the final sentence. If the browser can’t access the microphone (some phones or browsers block it), it records the audio as a file instead and sends it to the server for processing.
Step 4: If the browser couldn’t transcribe, the server does it.
When the audio file arrives at the server, a speech-to-text model called Nemotron listens to the recording and converts it to text. This takes about a second and a half at most. Once the text is ready, it’s passed to the next step just like a normal transcript.
Step 5: The transcript gets an intelligent reply.
The transcript is sent to the LLM (the AI brain) — a model called LFM2.5 that runs on the GPU. The AI reads the conversation so far and writes a helpful reply. If the GPU is busy handling audio, the system automatically switches to a backup model running on the CPU so the user never waits too long. The reply text is sent back to the server.
Step 6: The reply is spoken out loud.
The server sends the reply text to a text-to-speech service called MiMo, which converts it into natural-sounding speech. The speech is sent back to the user’s browser, which plays it through their speakers while also showing the text in a chat bubble. The whole round trip — from the moment the user releases the mic to hearing the reply — takes about 3 to 5 seconds.
Steps 7–8: After the conversation, the system does research.
When the user ends the conversation (by leaving the page or after 10 minutes of silence), the backend triggers a research pipeline. It sends the full transcript to Doubleword’s async service, which spawns five research agents in parallel. Each agent researches a different topic: the prospect’s tech stack, similar past projects, pricing, open-source alternatives, and compliance requirements. All five work at the same time and finish in about 1–2 minutes. A root agent collects their findings and writes a single summary. This summary is then saved to Twenty CRM as a lead record, and the transcript is stored in a vector database for future reference. If the CRM is temporarily down, the summary is saved in a queue and retried later.
Step 9: Every morning, a daily digest is prepared.
At 6 AM UTC, a scheduled job uploads all of yesterday’s conversations to Doubleword’s batch service. The batch service processes them over the next few hours (there’s no rush — the developer doesn’t read them until 9 AM anyway). When processing is complete, the results are written to Twenty CRM as a per-developer digest: top three prospects, open follow-up items, recurring objections, and a one-paragraph summary of each conversation.
The Doubleword API design in detail:
As discussed before the workflow, here’s the example workflow on how the various API’s interact with the hosted vLLM setup.
1. Realtime API’s:
Once the user’s IVR session starts, we need to address the queries that Hermes agent has during the discussion in order to respond based on the dynamic queries to get the context of user’s profile / project. here is the example codebase syntax to implement the realtime sequence query.
from openai import OpenAI

client = OpenAI(
    base_url="https://api.doubleword.ai/v1",
    api_key=os.environ["DOUBLEWORD_API_KEY"],
)

resp = client.chat.completions.create(
    model="Qwen/Qwen3.5-4B",  # 1 ms TTFT, 0.05/0.08 per 1M in/out
    messages=[
        {"role": "system", "content": "You are Hermes..."},
        {"role": "user",   "content": transcript},
    ],
    max_tokens=256,
    temperature=0.7,
    service_tier="realtime"
)
As shown in pricing (and later wrt the benchmark comparison), these prices are well comparable vis a vis other parameters.
2. Async (flex) — per-session CRM enrichment
After the 5-minute session ends, Sarthak spawns **5 parallel sub-agents** (cultural history, tech stack benchmarks, similar past projects, pricing research, open-source alternatives) and feeds the results into a root agent that synthesises the final note.
# Each sub-agent — run concurrently
# for thread in ..... either having threaded response.
resp = client.responses.create(
model=”Qwen/Qwen3-VL-235B-A22B-Instruct-FP8”,
input=f”Research angle: {angle}\n\nTopic: {transcript}”,
service_tier=”flex”,
)
The service_tier=”flex” flag tells Doubleword to start the work ~1 minute at flex rates getting 25–50% discount wrt the realtime screening. The response returned via the standard OpenAI Responses API contract; we wait it from a single async caller per sub-agent.
The pattern Doubleword recommends the pre-loaded context pattern that combines the instant parallelism of task and doing horizontal scaling (rather than implementing the remote scaling) : thus for each task we spawn 5 sub-agents that each finish in 2 async rounds rather than 1 agent doing 10 sequential search-and-read cycles. All sub-agents across all branches are enqueued together. Thus this high-throughput backend processes them concurrently, turning a 10-step pipeline into 2 effective wall-clock rounds.
3. Batch (24h SLA) - daily call digest
Every morning at 06:00 AM IST, Sarthak uploads a JSONL file of yesterday’s sessions and asks for a per-developer digest: top three prospects, open follow-up items, recurring objections, with a one-paragraph summary of each sections (combined with the web search tools like the ).
# 1. Build JSONL
with open("daily.jsonl", "w") as f:
    for session in sessions:
        f.write(json.dumps({
            "custom_id": session["id"],
            "method": "POST",
            "url": "/v1/chat/completions",
            "body": {
                "model": "Qwen/Qwen3.5-4B",
                "messages": [
                    {"role": "system", "content": DIGEST_SYSTEM},
                    {"role": "user",   "content": session["transcript"]},
                ],
            },
        }) + "\n")

# 2. Upload
file = client.files.create(file=open("daily.jsonl","rb"), purpose="batch")

# 3. Submit
batch = client.batches.create(
    input_file_id=file.id,
    endpoint="/v1/chat/completions",
    completion_window="24h",
)

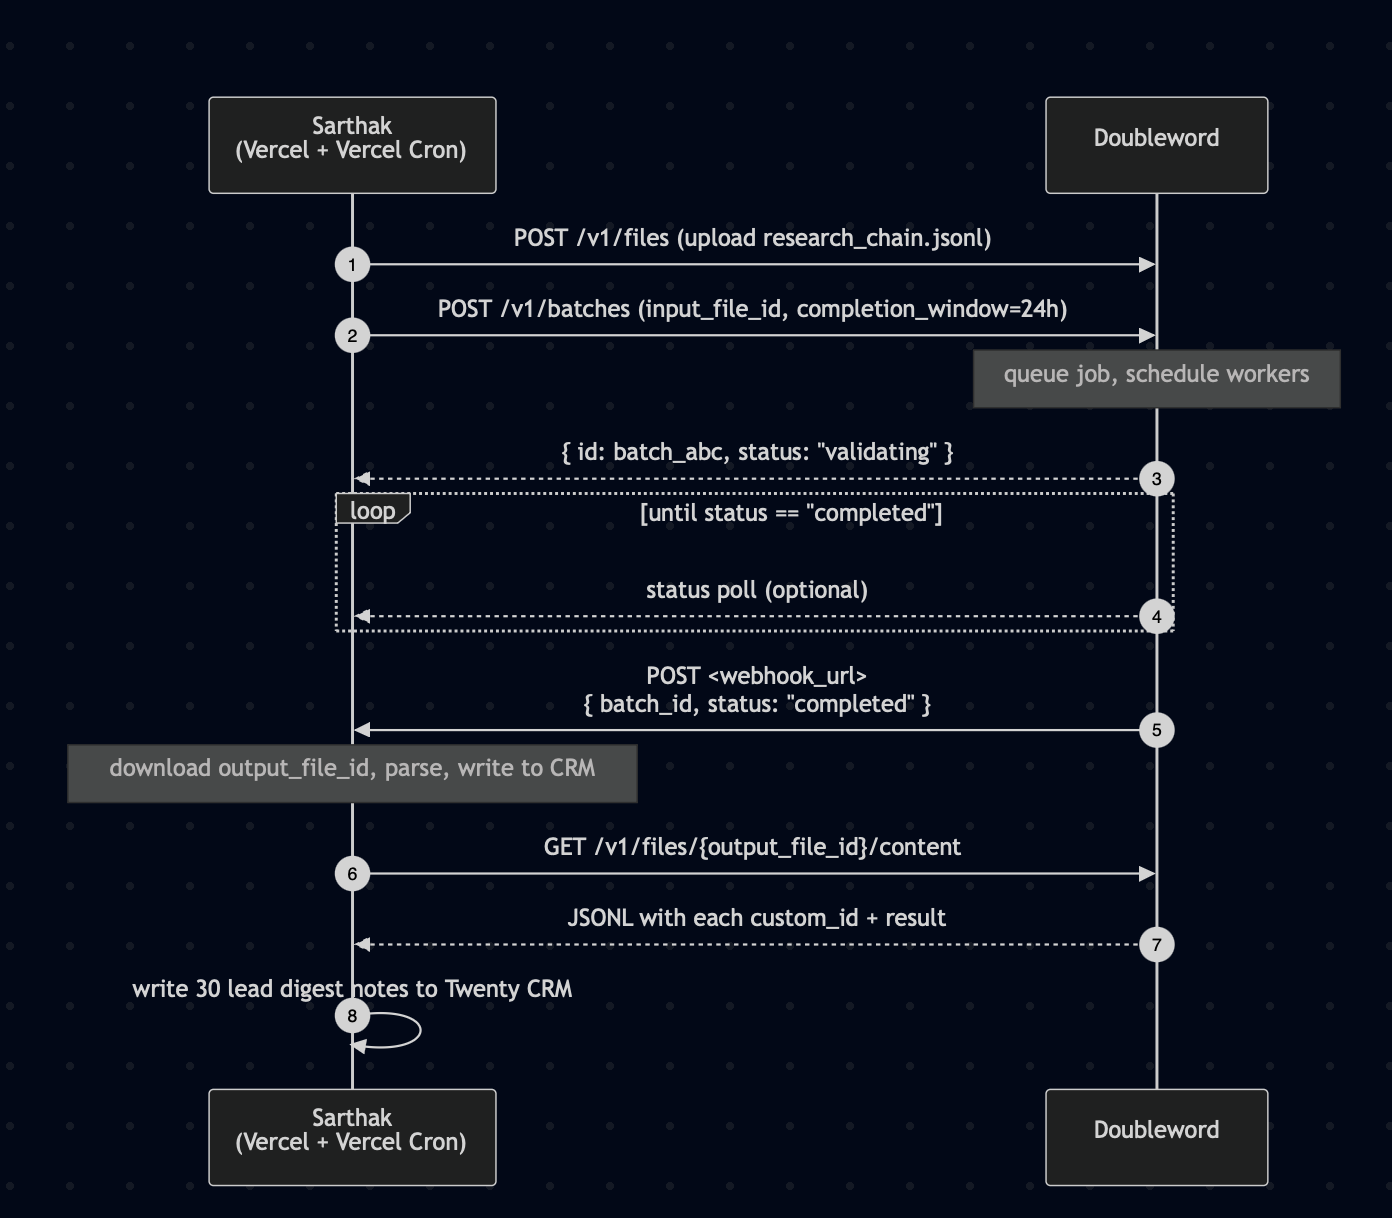
# 4. Polling / using webhook (for multithreaded verification).
while batch.status != "completed":
    time.sleep(300)
    batch = client.batches.retrieve(batch.id)
At batch pricing, the entire daily digest costs pennies even for the batch of 100+ sessions. Thus the 24h SLA is fine for the developer reads the digest during specific time slot. in case if you are using webhook for asynchronous calling of the batch updates , it will be integrated as follows:
Final benchmark
Taking the above architecture example and then running the benchmark review (script here), with the following considerations for the testing for 120 calls @ 5 mins / call on qwen-3.5 provides the following overall costs:
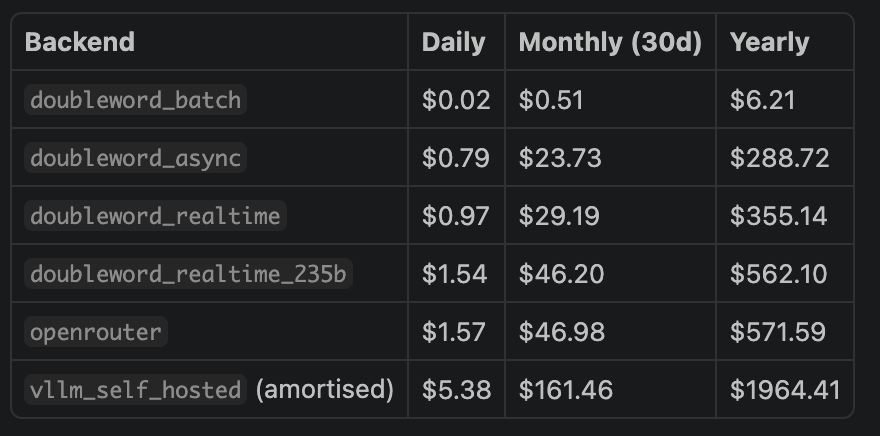
💵As shown that it’s the humongous savings, beating 20-100x with the other counterparts.
Note:
vllm_self_hosting is just considering that the hosted instance remains idle during the off working hours (9pm-9am) hosted on spot GCP instance for 16GB T4 GPU with the focus for summarization + twentyCRM agentic task).
Also for now the volume of the lead calls are taken low in the initial stage, we can extrapolate that eventually if the call volume increase more than 1000 calls , the cost on “vllm_self_hosted“ will be comparable vis a vis doubleword.
Acknowledgements
This article was possible thanks of following resources/ teams :
The Doubleword team: Superb team behind their async / flex inference API’s with very dynamic team helping upcoming startups like us with resources (including their technical blog providing up to date performance improvements in the inference space) and providing initial 50$ equivalent credits to test their backend services. also checkout their GitHub page for updates across architecture patterns / inference services giving open source recipes on how to build SOTA architectures.
The Twenty CRM team —> For building an open-source CRM that actually fits agentic workflows and provides notion like CRM management with API access. checkout their free open source version here.
Open source model architectures:
Liquid AI: Using their LFM-1.2B STT model in order to generate high performing voice detection.
Nemotron 3.5 0.6B: The 600M-param Cache-Aware FastConformer-RNNT that can do 240 concurrent streams ( from one H100 and powers our server-side ASR fallback).
The Xiaomi team: For MiMo-V2.5-TTS, the only TTS API I’ve found with style-instruction + audio-tag control that doesn’t leak special tokens.
Resources:
Live demo: https://frontiertech.vercel.app/contact —> add your personal credentials and then you’ve the onboarding voice agent starting discussions (with possibility to click and interact responsibility from your side for 5 minutes).
Code: https://github.com/Frontier-tech-consulting/Sarthak .
(NOTE: for now the aspects of knowledge base nuance / vector and memory recall are some of the engineering choice that we’re finetuning in order to release our first self hosted V1 ).
Final thoughts
Hence If you’re building a either building a real time inferrence or any other low SLA usecase: background-research pipeline; the lesson is the same: don’t route all your LLM calls through the realtime tier. Pick the most optimized SLA API’s and don’t get bothered on the rendering aspects (like the serverless GPU throttling, warming period and other nitty gritty of AI performance engineering).
Thanks for reading and following up on this article, if you are interested to learn more on the real applications of various open source pipelines / practical architecture decisions for your real time use cases: please subscribe and share your feedbacks here ( or also share your requirements for your next AgentOps project do schedule a call via the agent described above ).